NVIDIA GTC 2026 Keynote: Agenda, Timestamps and Where to Start
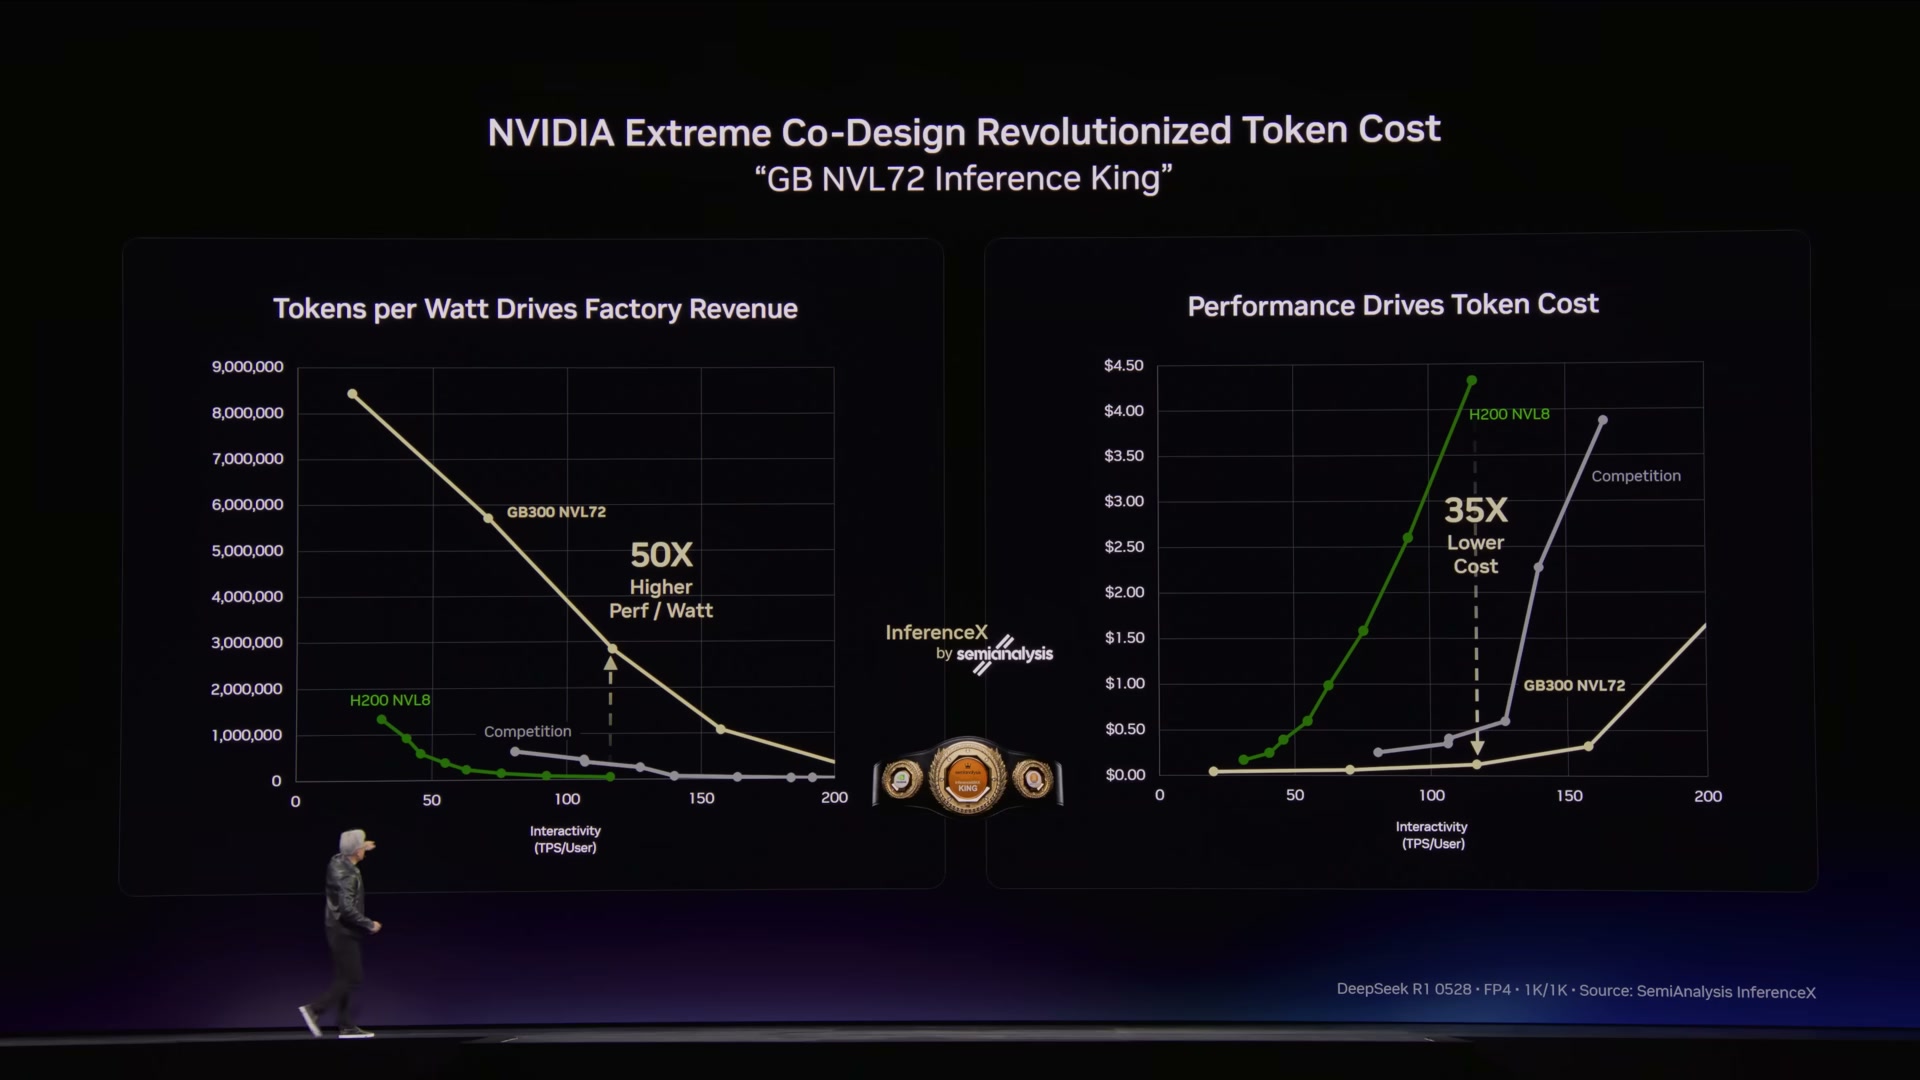
The unit of the talk is tokens per watt, not FLOPS. From 1:01:13, Jensen describes every data center as a power-limited token factory whose revenue is set by throughput per megawatt. Explainer.
CUDA turns 20. Jensen frames the anniversary around SIMT programming and the new Tiles feature for programming Tensor Cores
Three shifts in two years drove demand: generative AI with ChatGPT, reasoning with o1 and o3, then agents with Claude Code (0:46:18). Each one multiplied tokens per task.
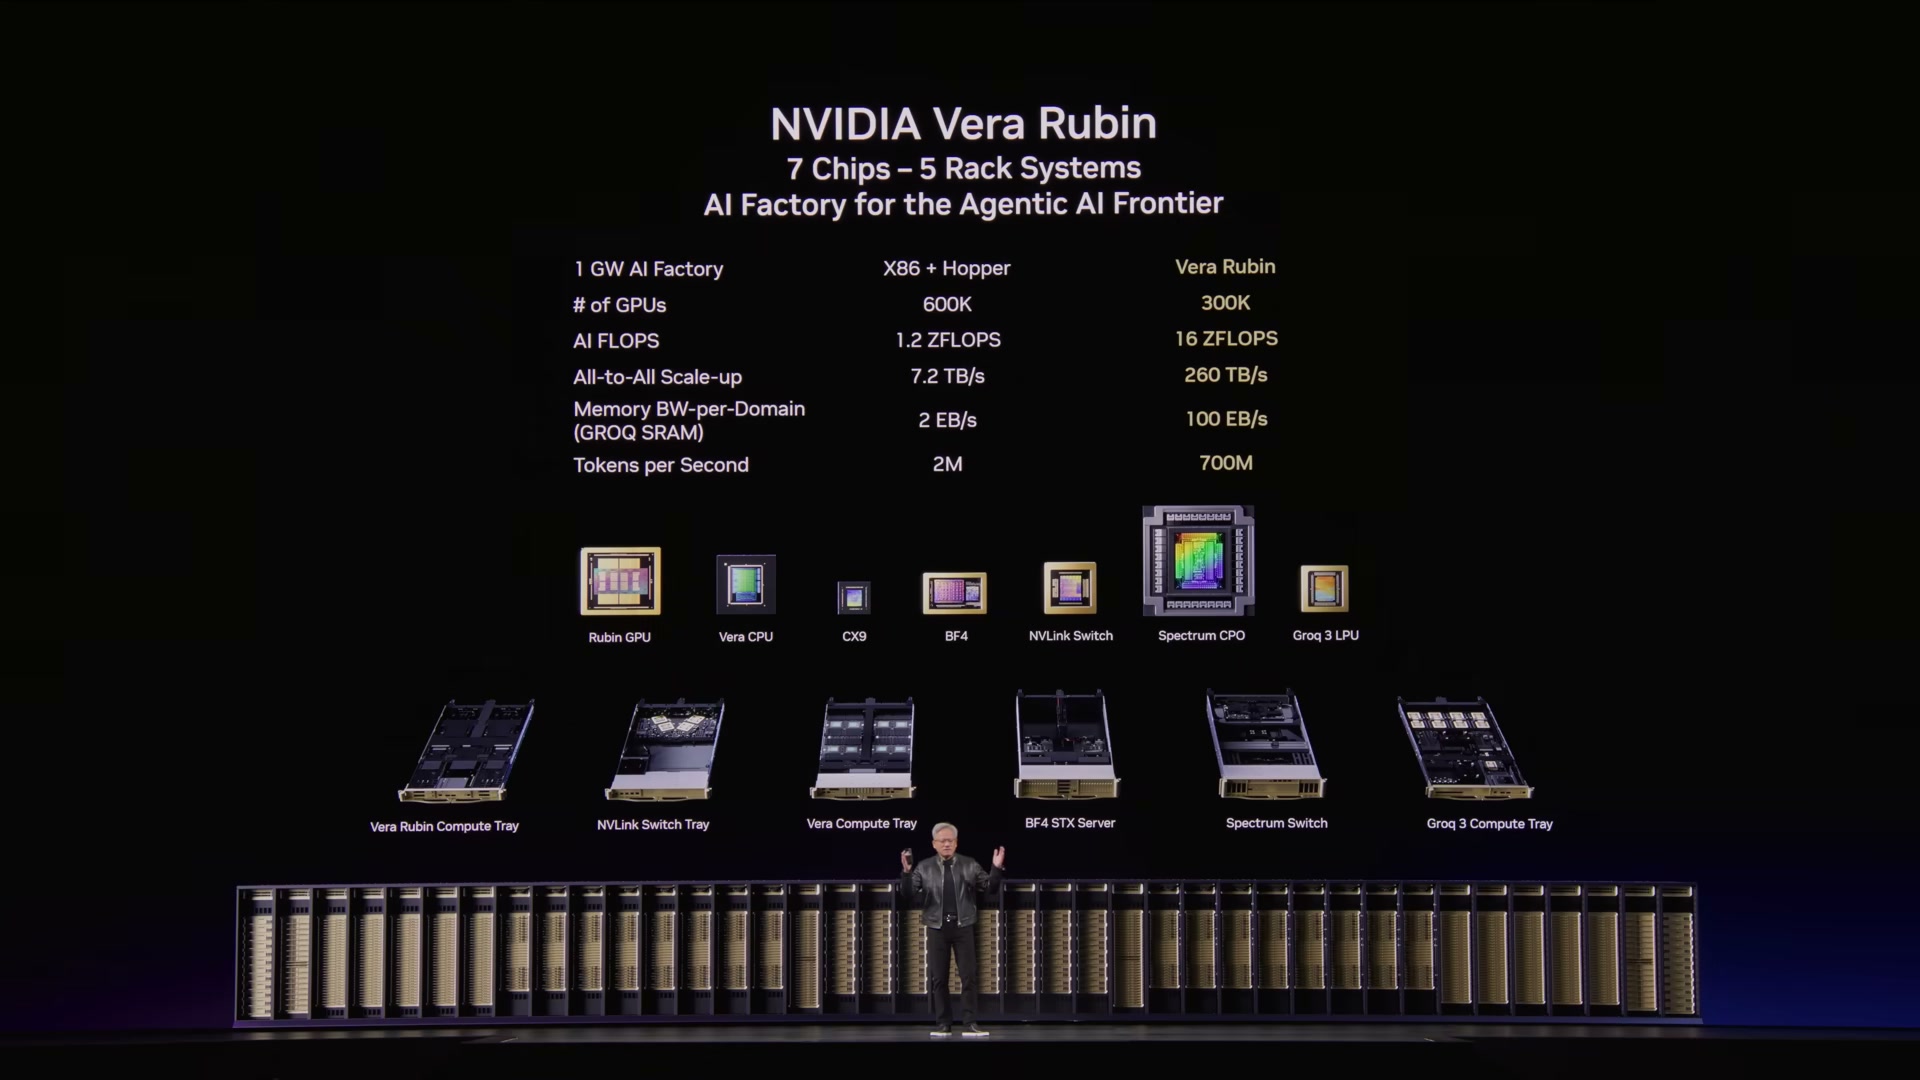
The unit of sale is now the AI factory, not the chip. Vera Rubin is pitched as seven chips and five rack types that NVIDIA designs together (1:11:12). That framing matters more than any single spec, because it is how NVIDIA argues against cheaper standalone accelerators.
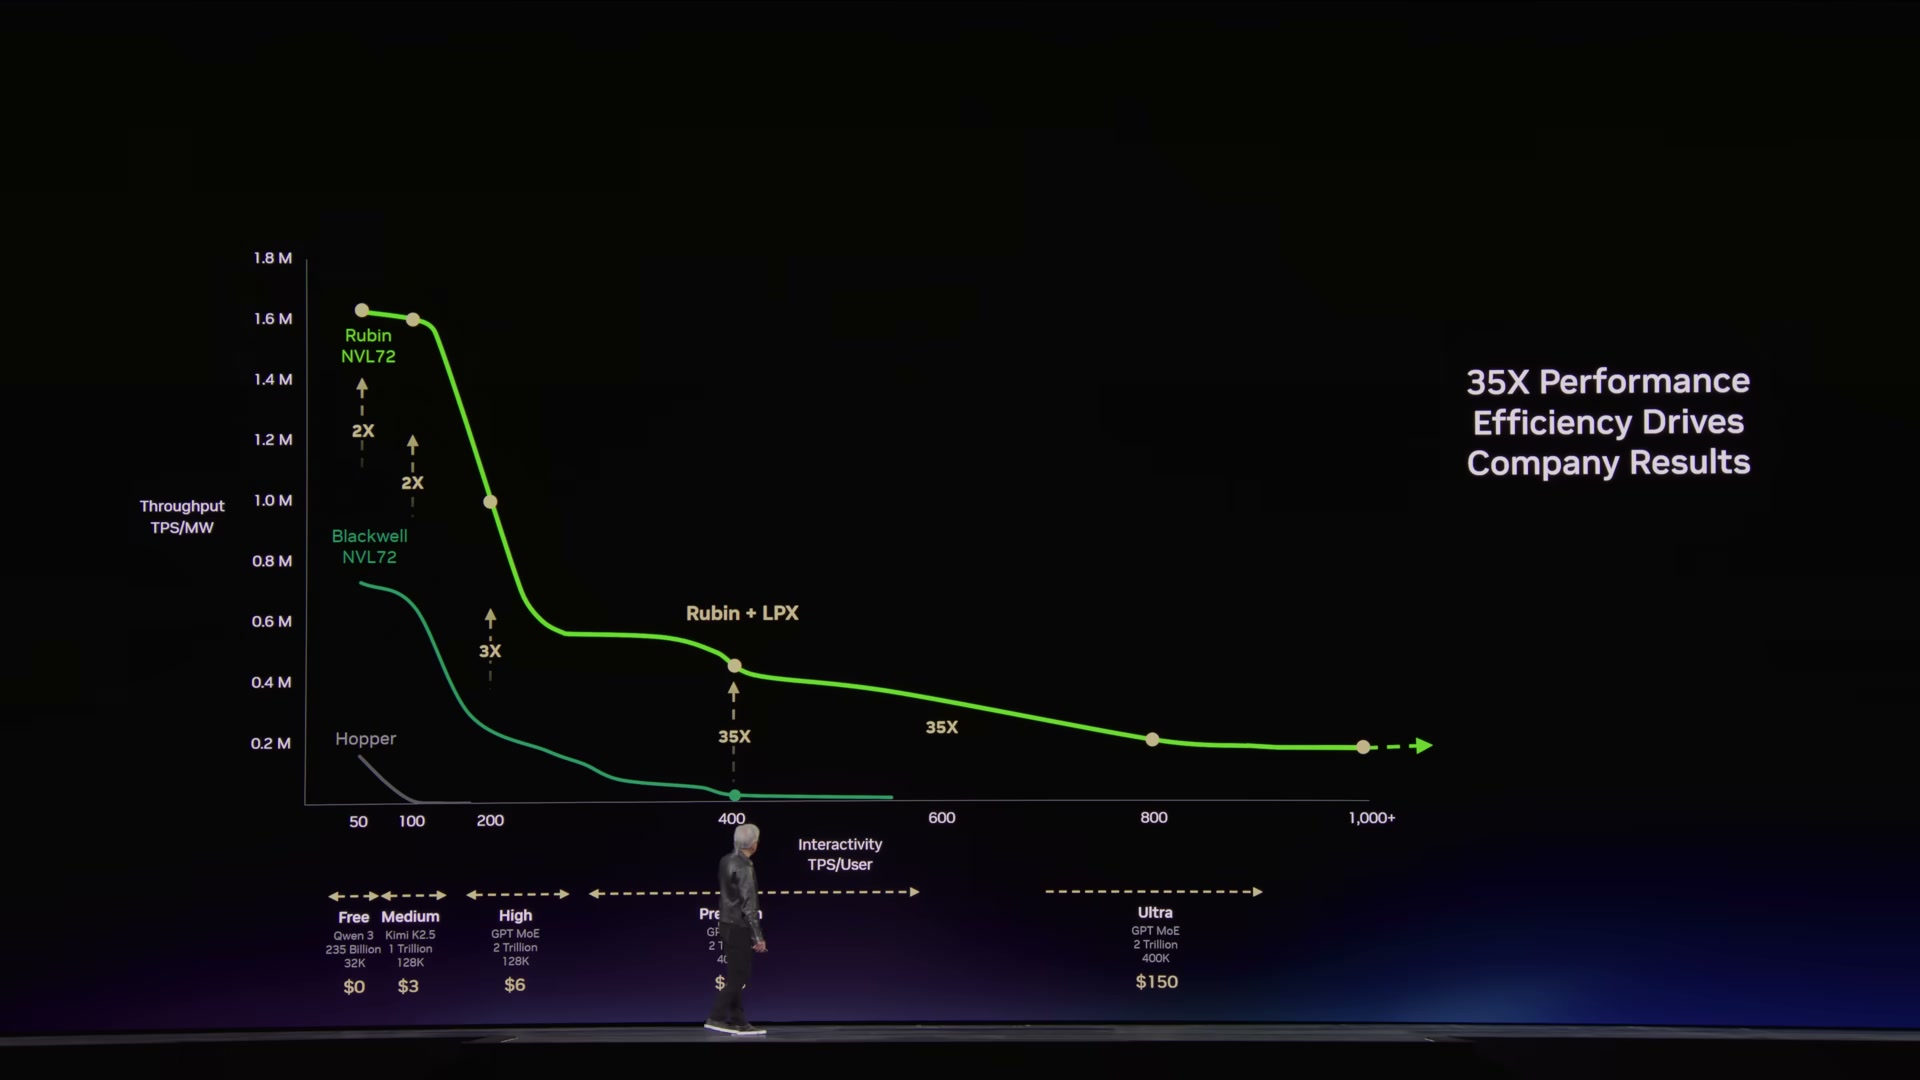
Tokens will be sold in tiers, like any maturing commodity. Jensen sketches free, $3, $6, $45 and $150 per million token tiers, each tied to model size, context length and speed (1:21:37). These are illustrative prices from a slide, not NVIDIA products.
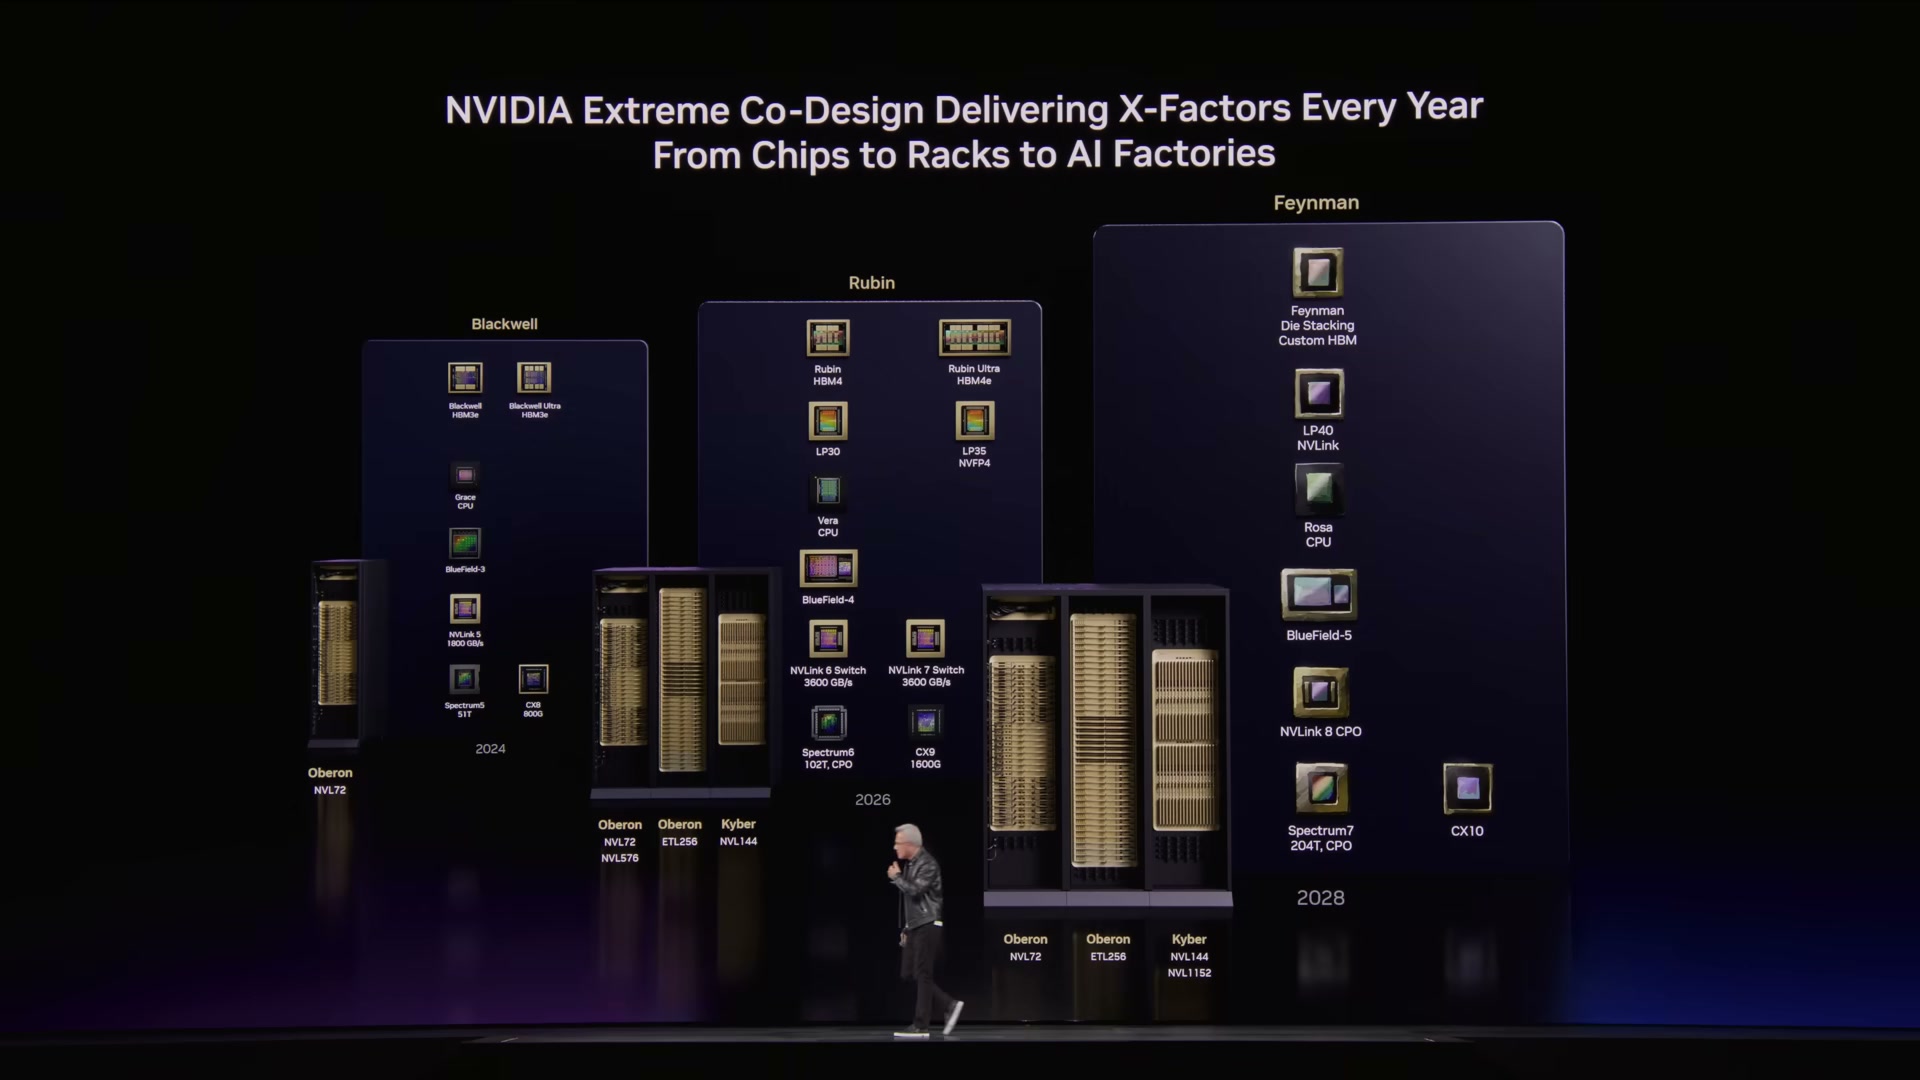
Vera Rubin is in full production alongside GB300. Jensen says every major storage vendor is joining the BlueField-4 ecosystem
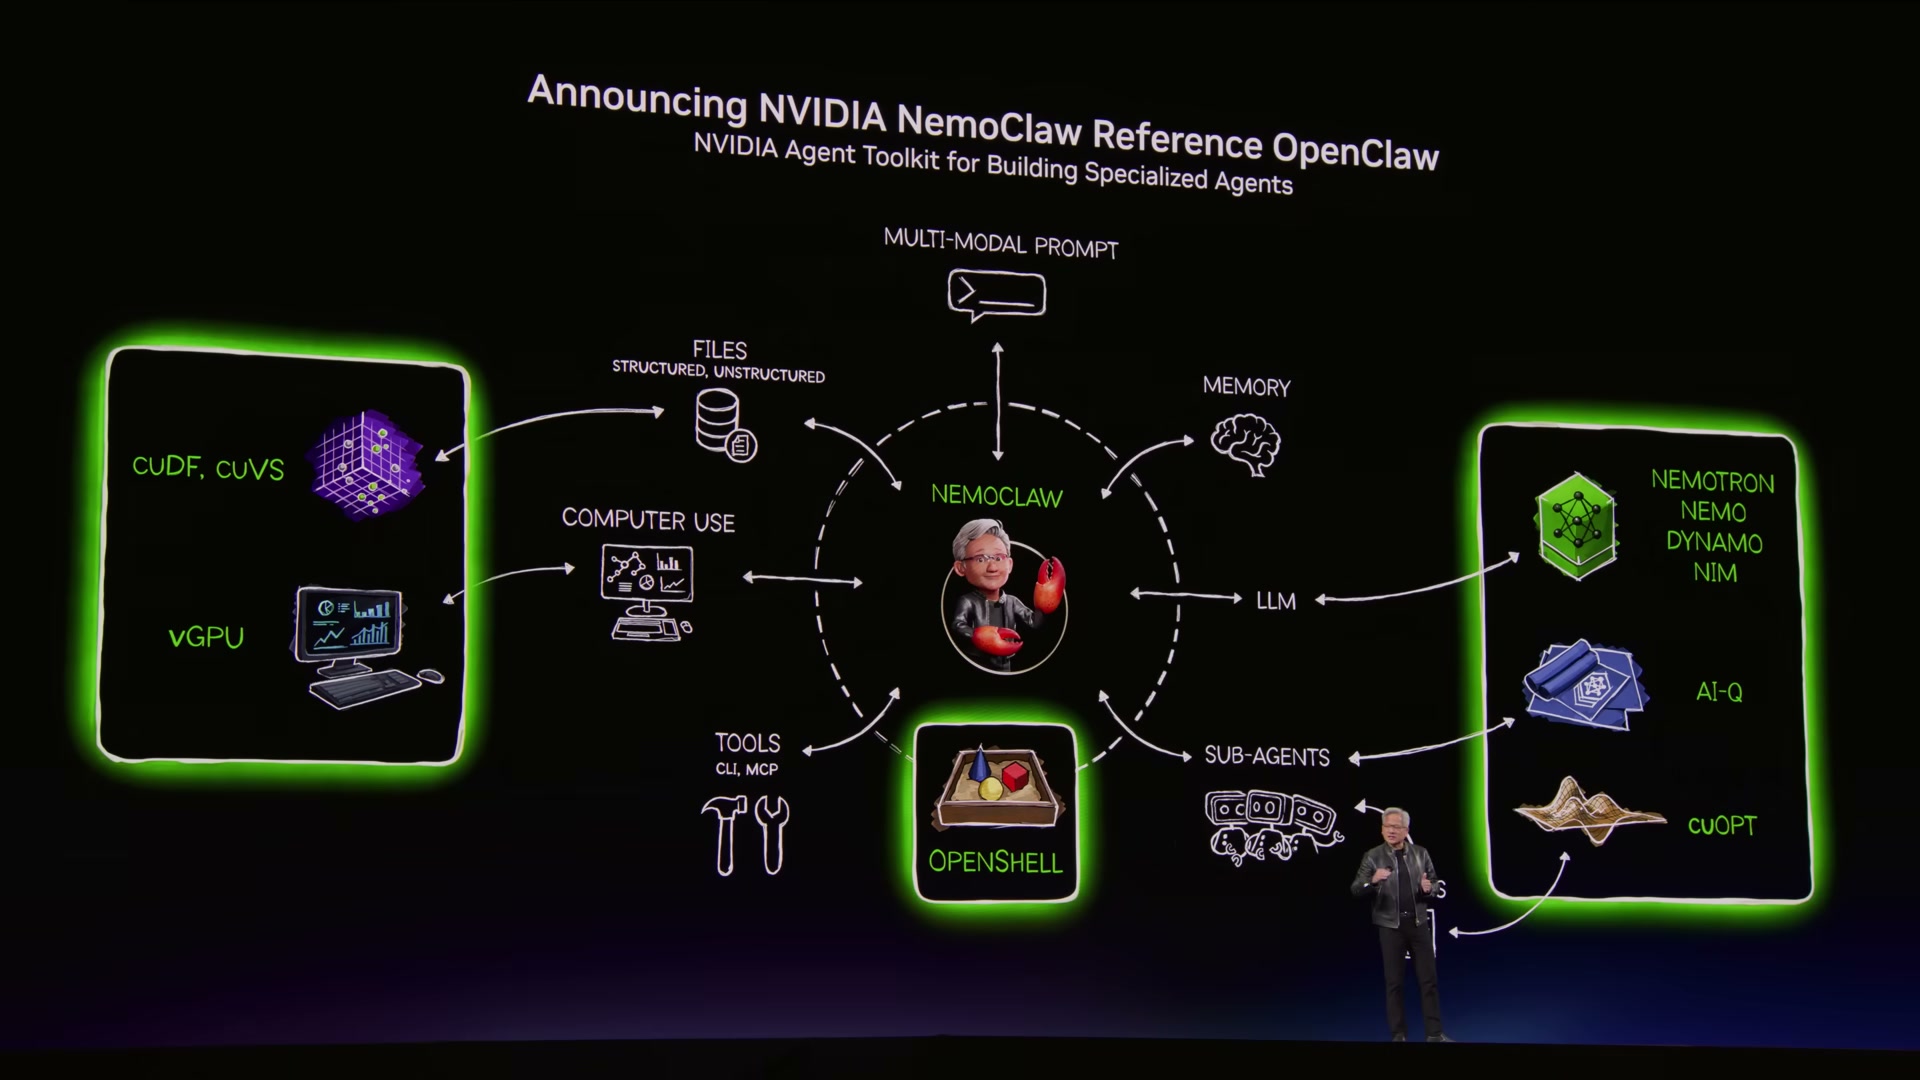
OpenClaw is not NVIDIA's; NemoClaw is. Peter Steinberger created OpenClaw. NVIDIA built NemoClaw, which installs Nemotron models and the OpenShell runtime on top of OpenClaw in one command
Six families, one pitch. Nemotron, Cosmos, GR00T, Alpamayo, BioNeMo and Earth-2 cover language, world models, robots, cars, biology and climate
Four new robotaxi automakers named on stage. Jensen lists BYD, Hyundai, Nissan and Geely; the official release lists BYD, Geely, Isuzu and Nissan
NVIDIA’s GTC 2026 keynote ran on March 16, 2026, at 11 a.m. PT in the SAP Center, San Jose. Jensen Huang spoke for a little over two hours; the official recording is 2:18:56 long. This page is the map: what each segment covers, where to click, and which of our notes go deeper.
Agenda
| Time | What happens | Our notes |
|---|---|---|
| 0:09 – 6:02 | Opening film, then Jensen frames the talk around three platforms and a five-layer AI stack. | Full notes |
| 6:02 – 16:15 | Twenty years of CUDA, the install-base flywheel, and the DLSS 5 neural rendering demo. | DLSS 5 and CUDA at 20 |
| 16:15 – 30:00 | Accelerated data processing (cuDF, cuVS), IBM watsonx.data, and cloud partner case studies. | Full notes |
| 30:00 – 43:00 | “Vertically integrated, horizontally open”: industry tour and the CUDA-X library film. | Full notes |
| 43:00 – 54:40 | AI-native companies, the “inference inflection”, and the order outlook through 2027. | Token economics |
| 54:40 – 1:07:56 | Tokens per watt as factory revenue, SemiAnalysis benchmark, Fireworks case. | Tokens per watt, explained |
| 1:07:56 – 1:20:00 | DGX history, then the Vera Rubin racks, Vera CPU, NVLink 6, CPO Spectrum-X, Rubin Ultra on Kyber. | Vera Rubin platform |
| 1:20:00 – 1:29:18 | Token pricing tiers and the throughput-versus-speed curve. | Token economics |
| 1:29:18 – 1:34:40 | Groq 3 LPX joins Vera Rubin through Dynamo’s disaggregated inference. | Groq LPX · Disaggregated inference, explained |
| 1:34:40 – 1:40:06 | Full production status and the roadmap: Rubin Ultra, LP35, Feynman, LP40, Rosa. | Roadmap |
| 1:40:06 – 1:46:32 | Omniverse DSX for designing and running gigawatt AI factories; Vera Rubin Space-1. | Full notes |
| 1:46:32 – 1:56:37 | OpenClaw as an “agent OS”, plus NemoClaw and OpenShell for enterprise use. | NemoClaw and OpenClaw |
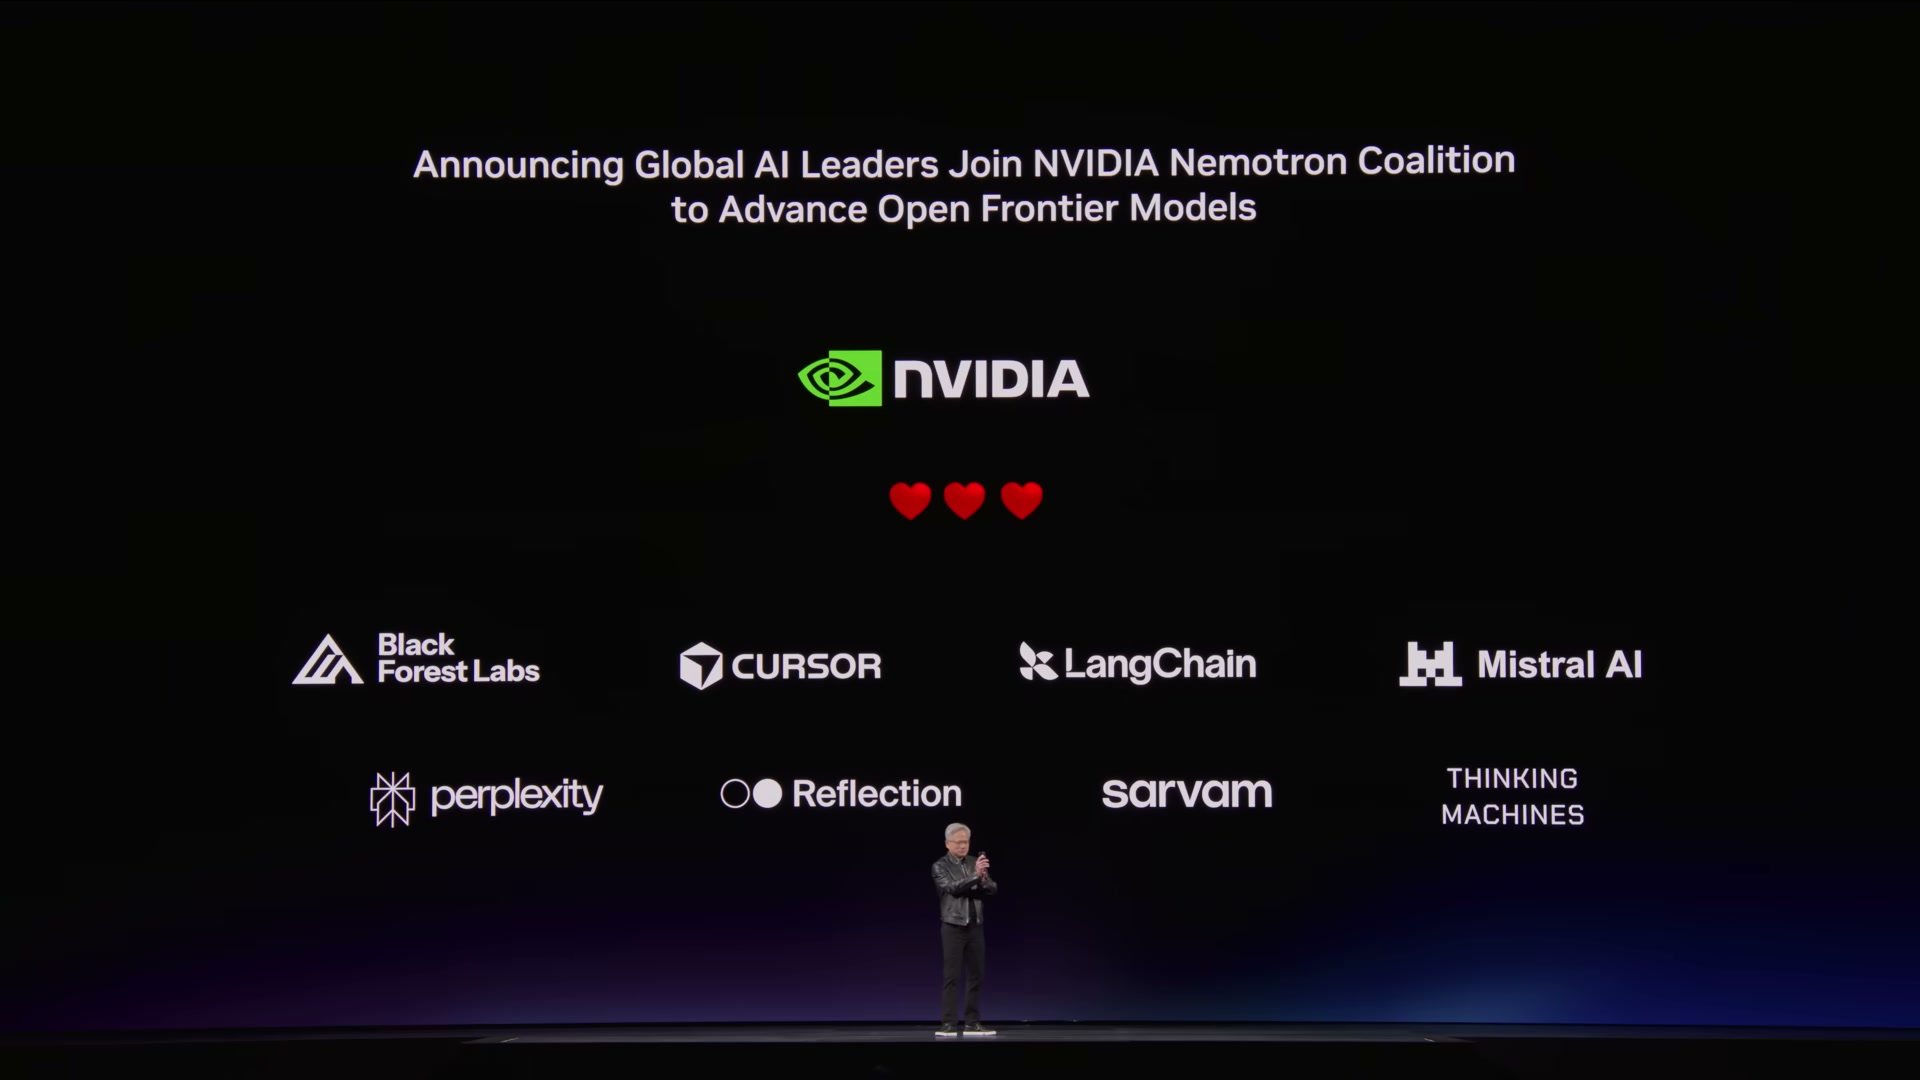
| 1:56:37 – 2:05:35 | Six open model families and the Nemotron coalition. | Nemotron coalition |
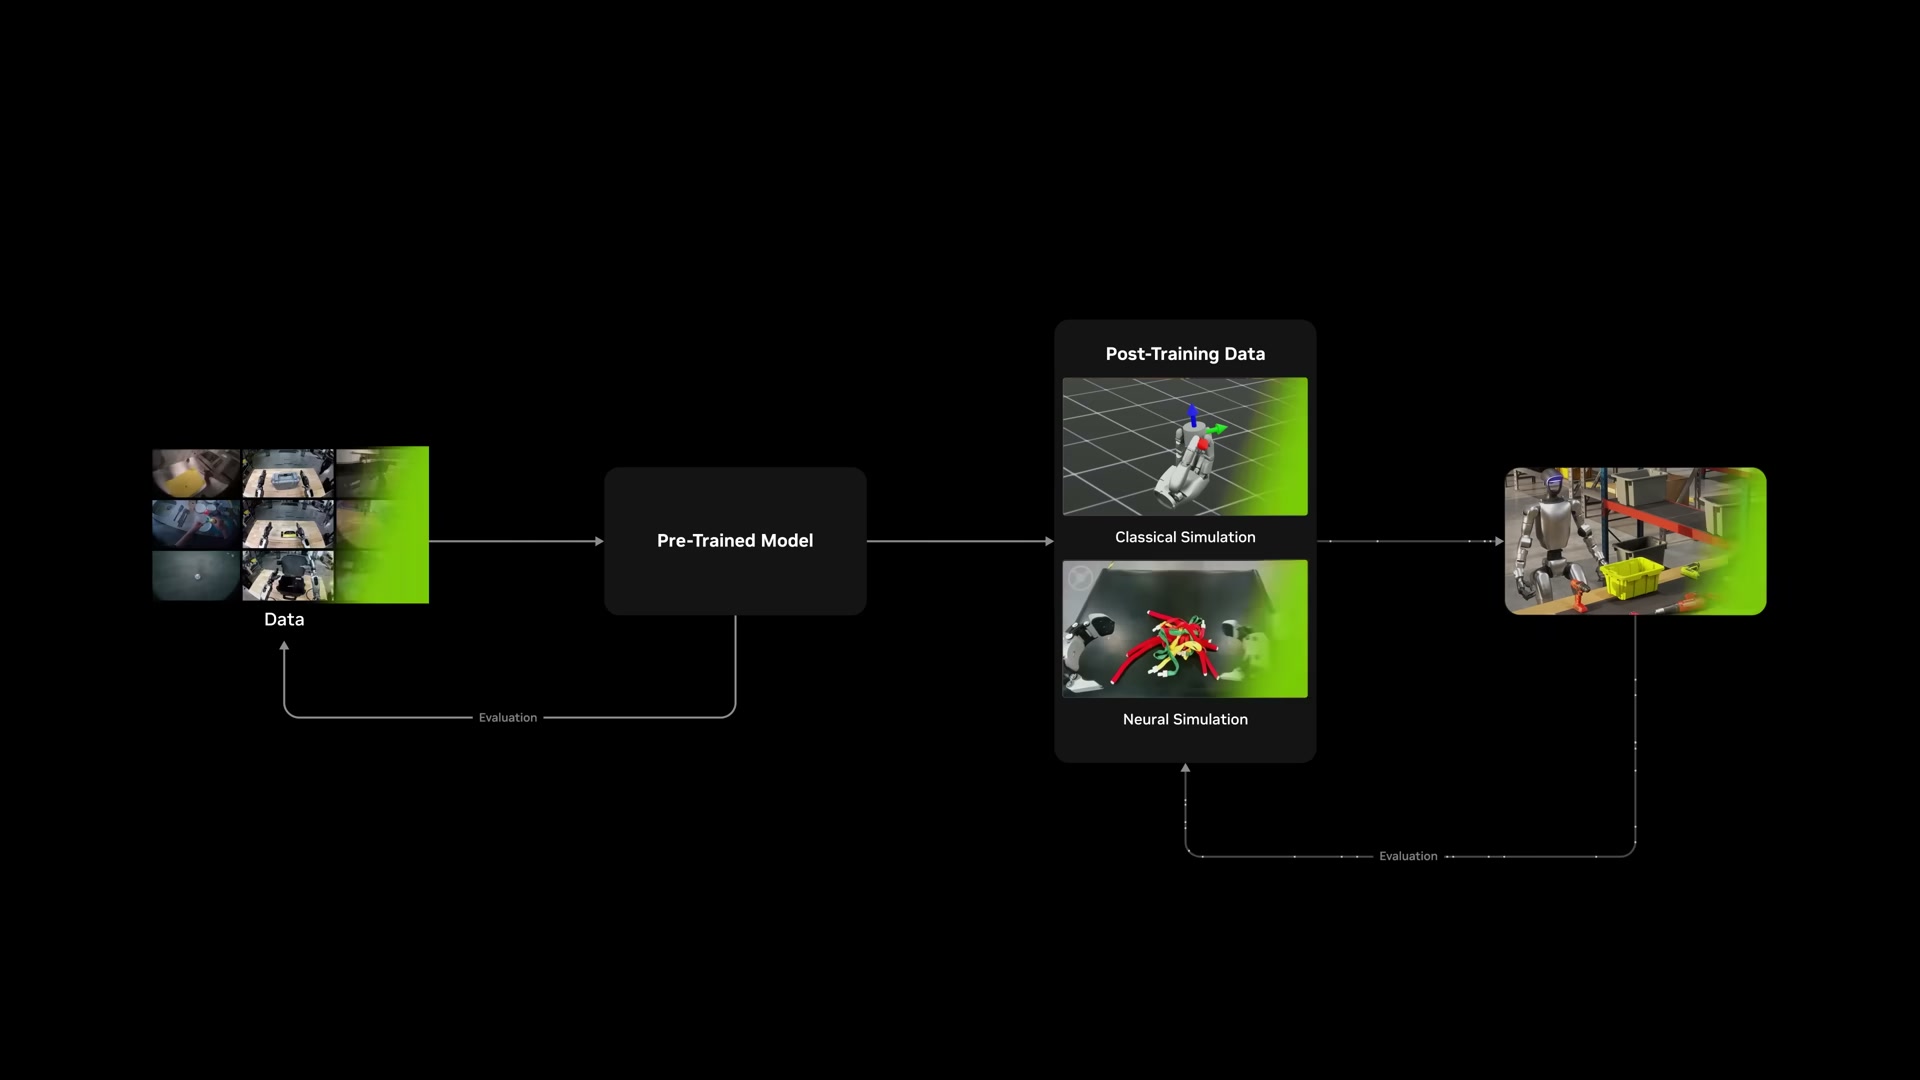
| 2:05:35 – 2:15:20 | Robotaxi partners, Isaac Lab and Newton, and the Olaf robot on stage. | Physical AI |
| 2:15:20 – 2:18:56 | Recap delivered as a song. Safe to skip. | — |
Start here
- Tokens per watt, explained. Every hardware claim in the talk is expressed in this unit, so read it first.
- Token economics and the inference inflection. This is the business case: why NVIDIA thinks inference demand keeps compounding.
- Vera Rubin platform, then Groq LPX and disaggregated inference. These are the products that are supposed to deliver that case.
- Roadmap: Rubin Ultra to Feynman. What ships after Vera Rubin.
- Pick by interest: agents and NemoClaw, open models, physical AI, DLSS 5.
If you want one page that walks the whole keynote in order, use the chapter-by-chapter notes.
What this event was really about
On the surface GTC 2026 was a product launch: Vera Rubin moved to full production and a new rack, Groq 3 LPX, appeared beside it. The more important change was the unit of account. Jensen spent most of the hardware hour on one idea: a data center is a power-limited factory, its output is tokens, and the only number that matters is how many tokens each watt produces at a given response speed. FLOPS barely came up. That framing lets NVIDIA argue that buying its newest system is cheaper than running an older one for free. It also shows where the company thinks competition will come from.
The second theme was specialization inside inference. A year earlier, Dynamo split prefill and decode across different GPUs. This year NVIDIA went further and split the decode step itself: attention stays on Rubin GPUs that hold the large KV cache, and the expert feed-forward layers move to SRAM-heavy Groq LPUs. That is an admission that one chip design cannot be best at both high throughput and very low latency. NVIDIA’s answer is to sell both chips and let its software decide which one does what.
The third theme was demand. The software half of the talk, covering OpenClaw, NemoClaw, the Nemotron coalition and robotaxis, served the hardware half. Agents that run all day, coding tools that burn millions of tokens per engineer, and robots trained on synthetic data all turn into more tokens. Jensen’s line was that NVIDIA is “vertically integrated, horizontally open”. The keynote was built to show both halves of that sentence, and to make the case that each one sells the other.
FAQ
When and where was the GTC 2026 keynote?
Jensen Huang delivered it on Monday, March 16, 2026, at 11 a.m. Pacific at the SAP Center in San Jose. The official recording on NVIDIA's YouTube channel runs 2 hours 18 minutes 56 seconds.
Which part of the GTC 2026 keynote should I watch if I only have 30 minutes?
Watch 54:40 to 1:36:29. That stretch covers the tokens-per-watt argument, the token pricing tiers, the Vera Rubin plus Groq LPX pairing and the roadmap, which is where almost all the hardware news sits.
What were the biggest announcements at GTC 2026?
Vera Rubin in full production, the Groq 3 LPX inference rack paired with it through Dynamo, a roadmap out to Feynman, the NemoClaw enterprise stack for OpenClaw, a Nemotron model coalition and four new robotaxi automaker partners.